
 Nguyễn Chính Ngọc Liên
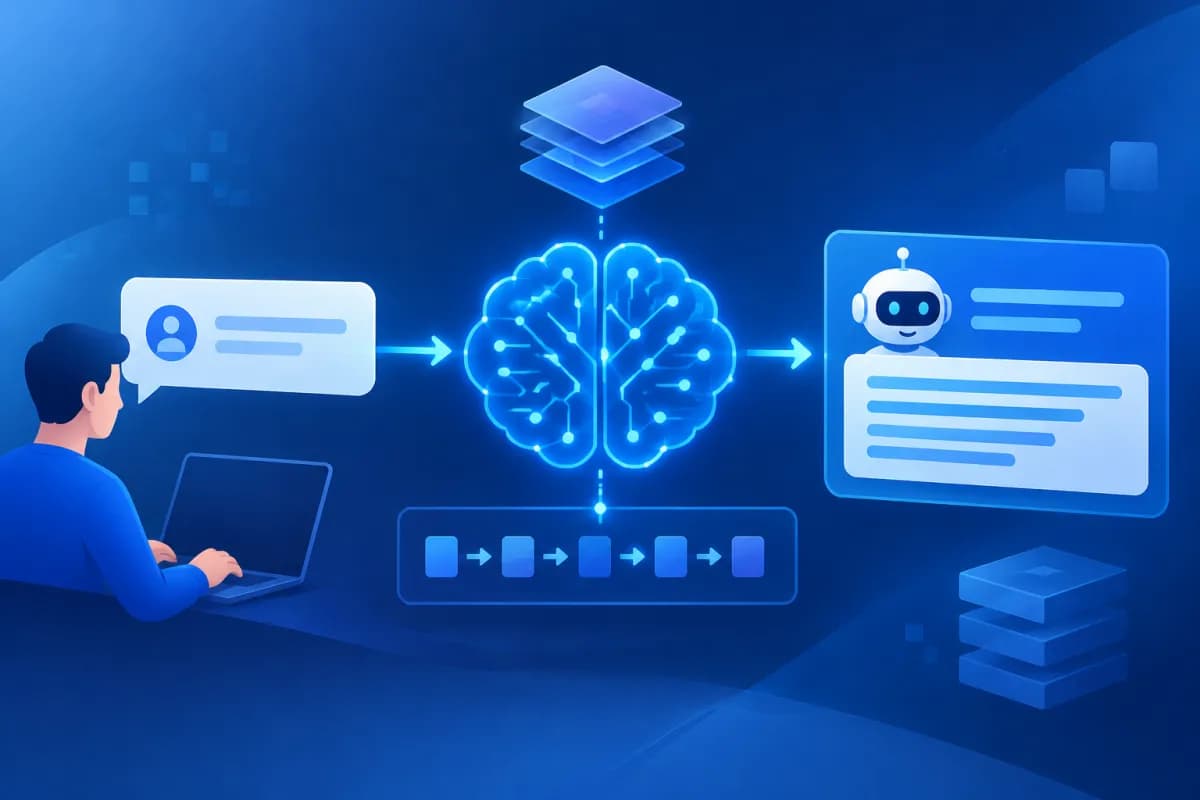
When a chatbot answers a question, a speech recognition app turns spoken words into text, or a recommendation system suggests a product, the AI model is performing a process called inference. This is the step where learned capabilities are put to use to process input data and produce a relevant result.
Understanding what AI inference is helps businesses see how AI applications work, as well as the factors that affect their speed, cost, and accuracy. This article explains the concept, the basic process, and how businesses can use inference effectively.
What Is AI Inference?
AI inference is the process by which a trained model receives new data and applies what it has learned to make predictions, classify, recommend, or generate an output. Inputs can include questions, images, audio, transaction details, or sensor data; the output depends on the model’s purpose and design.
For example, an image recognition model can classify a picture as a dog or a cat. A demand forecasting system can estimate how many products to prepare for the following month. With a large language model, the input might be a user’s question, and the output is a text-based answer.
Inference does not mean that a model thinks like a person or independently understands all information in a broad sense. The model performs calculations based on its structure, parameters, and patterns learned during training. Results are generally predictions with a certain level of probability, so they can be useful but may still need to be checked in important situations.
How Is Inference Different from AI Training?
Training and inference are related stages with different purposes. During training, a model processes large amounts of data to adjust its parameters, learning to recognize patterns or generate outputs according to a defined objective. This process typically requires significant computing resources and can take anywhere from minutes to several days, depending on the model’s scale.
During inference, the trained model receives new data and generates a result without having to be retrained from scratch for each request. For example, a model for detecting unusual transactions can be trained on historical data and then use inference to assess new transactions.
- Training: The model learns from data and adjusts its parameters to improve its ability to perform a task.
- Inference: The model uses its existing parameters to process input and produce a prediction or content.
- Fine-tuning: The model is further adapted using specialized data or instructions; this is not required for every inference request.
Distinguishing between these two stages helps businesses identify what they actually need. If a business wants to add AI to its website to answer frequently asked questions, it can use an existing model and deploy inference. If the model needs to better handle specific terminology, processes, or data, the business can consider fine-tuning, connecting internal data sources, or other customization options.
How Do AI Models Generate Answers Through Inference?
The exact process varies across language, image, and forecasting models, but it can be understood through the following basic steps:
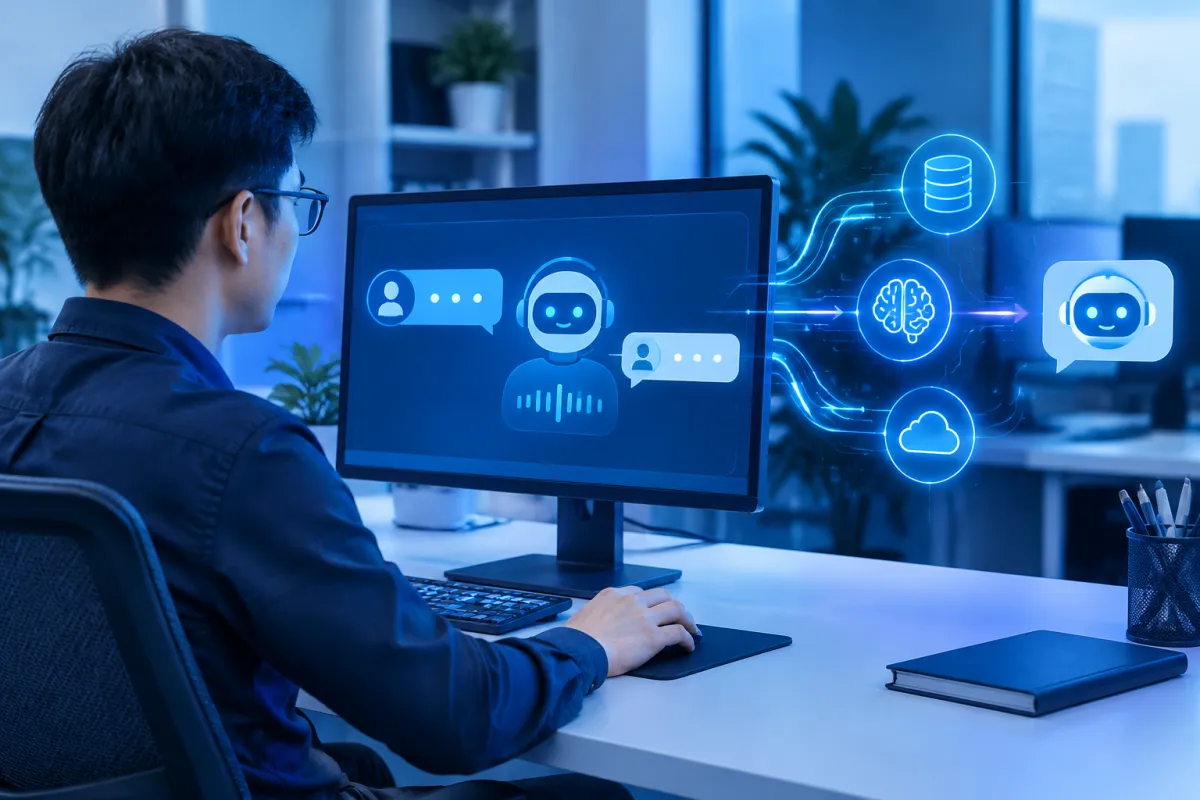
- Receive and normalize the input: The system receives a request and converts the data into a format the model can process. Text questions are often split into smaller units called tokens. Images may be converted into numerical representations.
- Pass the data through the model: The input is processed using computational layers and parameters established during training. The model identifies relationships that may be relevant to the task.
- Calculate the result: The model generates scores, probabilities, or representations for possible outputs. In a classification model, scores can be used to select the most likely label. In a language model, the system predicts the next token based on the context.
- Generate and finalize the output: The model may generate multiple tokens in sequence to form an answer, or return a label, forecast, or recommendation. The application can check the format, apply safety rules, and display the result to the user.
For example, when a user asks a chatbot, “What is the store’s return policy?”, the question is converted into input for the model to process. The model generates content based on the available context or supplied documents. If the application is connected to a company knowledge base, the system can find relevant information and add it to the context before the model responds. Combining retrieval with a model is commonly called retrieval-augmented generation (RAG). It can help keep answers grounded in documents, but it does not guarantee that errors will be eliminated entirely.
With generative models, users can often adjust settings such as output length or randomness. Higher randomness can produce more varied wording, while lower randomness generally leads to more consistent results. The specific effect depends on the model and how the provider has implemented it.
Factors That Affect Inference Quality and Speed
Inference results depend on more than just the model’s name. Data quality, how a request is phrased, hardware resources, and application design can all affect the user experience.
- Input quality: Clear requests and complete, correctly formatted data give the model a better basis for processing. Missing or contradictory information can lead to inaccurate predictions.
- Model capabilities and scope: Each model is suited to particular tasks. A general-purpose model can handle a wide range of questions, while a specialized model may be more effective for a specific task.
- Available context: Reference documents, conversation history, or product information can help the system provide more relevant answers. However, the data provided should be kept up to date, and access should be controlled.
- Computing resources: Hardware, model size, input length, and the number of simultaneous requests affect latency, scalability, and operating costs.
- Evaluation and testing: Models should be evaluated using data that reflects real-world use cases. A result that sounds plausible is not necessarily correct or aligned with company policy.
For language models, an incorrect but convincing-sounding answer is often called an “AI hallucination.” To reduce risk, businesses should limit the scope of responses, prioritize trustworthy data sources, test challenging scenarios, and include human verification for important decisions. A model’s high confidence score should not be treated as proof that its output is correct.
Applying AI Inference in Business Operations
Inference delivers direct value in many AI applications that customers and employees use every day. Businesses can start with a specific task that has clear input data and evaluation criteria, rather than adopting AI simply because it is a trend.
- Customer service: Chatbots can classify questions, suggest answers, or help find product information. More complex issues can still be escalated to an employee.
- Marketing and sales: Systems can recommend content, segment customers, predict the likelihood of conversion, or help draft advertising copy. Content should be reviewed to maintain the brand voice.
- Operations and supply chain: Models can forecast demand, detect anomalies in data, or help optimize inventory levels.
- Document processing: AI can extract information from invoices, contracts, and forms, reducing manual data entry. The process should include checks before the data is used for important business operations.
- Digital products: Web or mobile applications can integrate recommendations, semantic search, image recognition, or AI assistants tailored to user needs.
When planning, businesses should define their objectives, user groups, data requirements, security needs, and evaluation metrics, such as processing time, the percentage of useful answers, or cost per request. They should also consider where sensitive data is sent, who has access to it, and which party is responsible if a result affects a customer.
Inference can run on cloud infrastructure, private servers, or on-premises devices. Cloud services are convenient when rapid scaling is needed, while private deployments may suit specific data control or latency requirements. The best option depends on the business’s scale, budget, technical capabilities, and regulations.
Conclusion
What is AI inference? It is the process by which a model uses what it has learned to process new data and generate predictions, classifications, or content. Understanding the difference between inference and training, along with the factors that affect results, helps businesses choose the right solution and set realistic expectations.
To apply AI effectively, businesses need to combine a suitable model with trustworthy data, oversight processes, and clear measurement goals. LilyTech works with businesses to advise on and implement technology solutions, from websites and mobile applications to ERP systems and digital marketing initiatives. Contact LilyTech to discuss an approach that fits your business needs and resources.

