
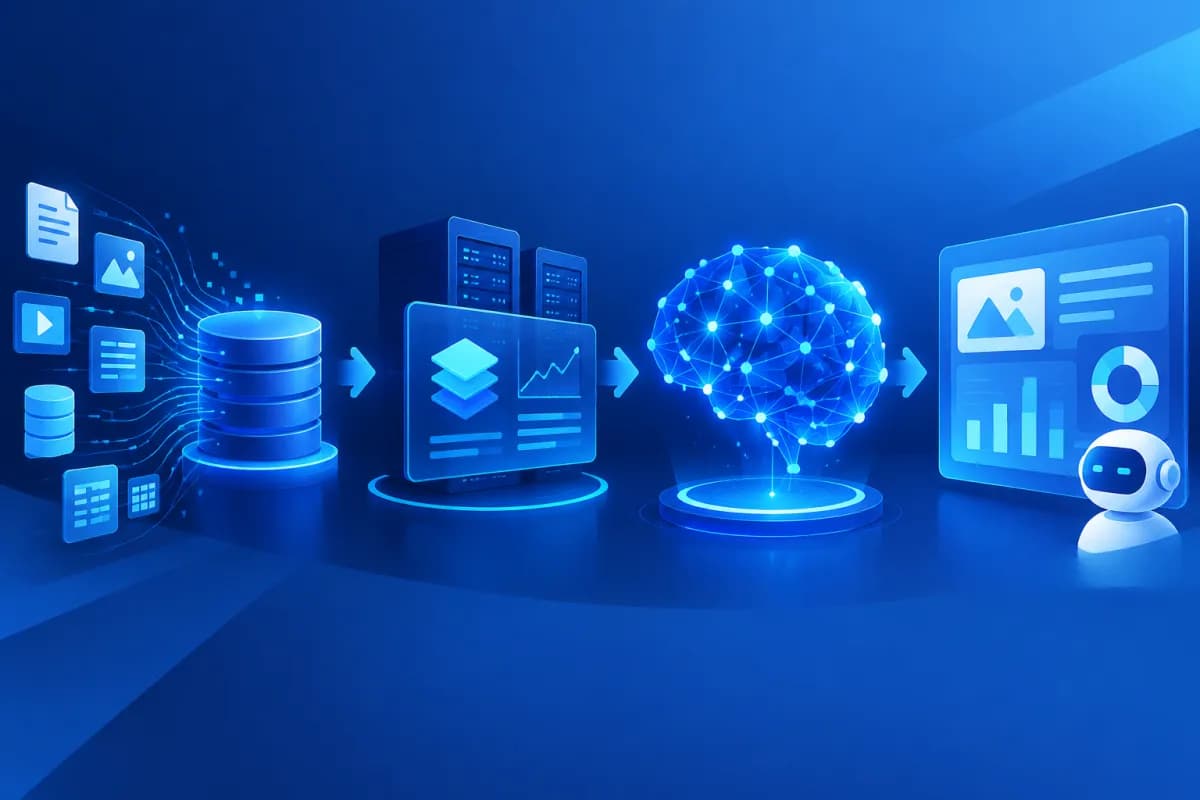
When exploring artificial intelligence, many businesses start with the question: what is an AI model, and how can they build one that supports real-world work? Put simply, an AI model is a system trained on data to identify patterns, make predictions, or generate content in response to a request.
Getting a model to work effectively takes more than choosing an algorithm or the latest technology. The process also involves defining the problem, preparing data, training and evaluating the model, and deploying it in a real-world environment. This article explains each step and highlights risks businesses should proactively manage.
What Is an AI Model and How Does It Work?
An AI model is the result of teaching a computer to learn from data. In the process, the system identifies relationships or recurring characteristics, then uses what it has learned to process new data. For example, an invoice recognition model can learn from thousands of invoice images to identify amounts, issue dates, and supplier names.
It is important to distinguish an AI model from an AI application. A model performs the prediction or generates the output, while an application is the complete product users interact with. It may include an interface, database, business processes, and an AI model. Integrating AI into a website or software, therefore, involves more than putting a model to work: it also requires designing how data is sent to it, how results are displayed, and how users review those results.
Models can perform many tasks, such as categorizing customer service requests, forecasting sales, recognizing images, recommending products, or drafting content. Each task calls for different data, evaluation methods, and levels of oversight. Businesses should start with a specific problem rather than choosing a technology first and then looking for a way to use it.
The Process of Building and Training an AI Model
1. Define the Problem and Success Criteria
Before collecting data, clearly describe what the model will do, who will use it, and what would make its output useful. For example, instead of setting a vague goal like “use AI for sales,” a business could define the problem as predicting which customer groups are likely to make another purchase within 30 days.
Success criteria should be tied to business outcomes: reducing request processing time, improving classification accuracy, or lowering the cost of a process. You should also define the system’s limits and the cases that need to be handled by an employee. This helps avoid investing in a model that performs well technically but delivers no practical value.
2. Collect, Clean, and Prepare the Data
Data is the foundation on which a model learns. Sources may include customer relationship management software, ERP systems, websites, apps, internal forms, or relevant public data. Before using it, businesses should check their rights to access and use the data, the intended purpose, and their obligations to protect personal information.
Raw data is often incomplete, duplicated, incorrectly formatted, or inconsistent. For instance, the same order status might be recorded in several different ways, making it difficult for a model to recognize what it means. Data cleaning typically involves handling missing values, removing duplicate records, standardizing formats, and checking for anomalies. Text data may need to be cleared of noise or labeled consistently.
The next step is to select features and label the data if the task requires examples with known answers. Label quality matters: if employees apply labels inconsistently, the model may learn from conflicting conclusions. Establish clear labeling guidelines, cross-check a portion of the data, and document the dataset’s source.
Data is usually divided into sets for training, tuning, and testing. The test set should reflect the data the model will encounter later and should not be used to tune the model during development. If the same information appears in multiple sets, evaluation results may be better than the model’s actual performance.
3. Train the Model
During training, an algorithm takes in data and adjusts its parameters to reduce errors against the defined objective. Depending on the task, the team may choose a traditional machine learning model, a neural network, or an existing generative AI model. The largest model is not always the right choice; cost, speed, explainability, and security requirements all need to be considered.
Training is typically a controlled process of experimentation. The team adjusts configurations, tracks results on appropriate datasets, and records the model version and settings. It is important to distinguish training a model from scratch from fine-tuning a pretrained model. For many businesses, using an existing model and adapting it to their own data and processes can save time, but they still need to carefully assess usage rights and suitability.
4. Evaluate and Test Before Use
After training, the model is tested on data it has not learned from. The evaluation metrics depend on the task. For classification, you might consider accuracy, how well the model identifies each group, and the rate of missed cases. For forecasting, you can measure the difference between predicted and actual values. Generative models should be assessed for relevance, consistency, hallucinations, and their ability to follow instructions.
Do not rely on a single overall metric. For example, a model may achieve high accuracy while still missing most rare but high-risk cases. In addition to technical testing, business users should review the results in real-world contexts, check edge cases, and decide what to do when the model is uncertain. Deploy only when both performance and risk are within acceptable limits.
Deploy, Monitor, and Improve the Model
Once it meets requirements, the model is connected to an application or operational process. Deployment may take place on cloud infrastructure, a private server, or through an API service, depending on security needs, technical capabilities, and budget. You will need to design how the system receives data, verifies access permissions, handles errors, and returns results to users.
Rather than rolling out the model everywhere immediately, a business can start with a limited trial. For instance, it could make the model available to a small group of employees or use it to handle a small share of requests while retaining the existing process for comparison. This approach helps uncover problems before they affect the entire operation.
After deployment, monitor both technical performance and business outcomes. Real-world data may shift with the seasons, customer behavior, or operational processes, causing prediction quality to decline over time. Set alert thresholds, keep version logs, record user feedback, and plan to update the data or retrain the model when needed. For decisions with a significant impact on customers, maintain a human review step.
Common Risks When Building an AI Model
- Biased or low-quality data: A model may produce inaccurate results if its data does not represent the intended use case, contains errors, or reflects bias. Check the data source, coverage, and balance before training.
- Information leaks: Customer, employee, or business-confidential data may be misused without proper access controls and retention policies. Limit access, anonymize data where appropriate, and verify your provider’s terms.
- Convincing-sounding but incorrect output: Some generative models can produce false or unsupported information. Do not assume their output is factual. Verify sources, limit the scope of responses, and require human approval for important content.
- Evaluation that does not reflect real conditions: Strong test results do not necessarily predict performance at scale. Test with data that resembles the real operating environment, edge cases, and different user groups.
- Costs and technology lock-in: Training, service, storage, and maintenance costs can rise with scale. Before investing, calculate the total cost of ownership, consider how easily you could switch providers, and plan for long-term operations.
Risk management is not just a technical team responsibility. Business, marketing, legal, IT, and leadership teams should agree on the intended use, who is accountable, how incidents will be handled, and how users will be informed when they interact with AI.
Conclusion
Understanding what is an AI model helps businesses recognize that AI does not automatically deliver results without suitable data and a well-managed implementation process. From defining the problem and preparing data to training, evaluation, and post-deployment monitoring, every step affects the system’s quality and safety.
Businesses should start with a specific need, set measurable success criteria, and run a suitably scoped trial before expanding. If you need advice on applying AI to a website, mobile app, ERP system, or marketing activities, LilyTech can help you assess your needs and recommend a suitable roadmap. Contact LilyTech to discuss a solution that fits your goals and available resources.

